Latest Articles
-
Does WebMCP `outputSchema` Help Agents Pick Better Tools?Consolidating WebMCP read tools while keeping descriptions under 500 characters hides the fields each tool returns from the agent. Here is what happened when I tested WebMCP's new outputSchema across single-turn lookups, multi-step chains, and multi-turn conversations.
-
Would Fine-Tuning Have Beaten Jev?The third post in my series on describing a classifier with Jev versus training one. This time I fine-tuned BERT on the same Jigsaw toxicity comments. With enough labels it ranks toxic comments better than Jev and the cloud-embedding models, but it needs about 500 labels to pass Jev, a GPU to train, and it misses almost every comment on the two rarest labels.
-
The Bouncer's Dilemma: Jev, k-NN, and MLP for Comment ModerationIn my last post, I skipped training a spam classifier and used Jev instead. Here, I compare Jev with a neural network and k-NN built from thousands of labeled comments in the Jigsaw toxicity dataset: how accurate each one is, how many labels they need, and what they cost to run.
-
Fighting Comment Spam Without Training a ModelStruggling with comment spam but lack the data for traditional AI? Uncover an ingenious method to automatically filter blog spam without the need for extensive datasets, complex machine learning models, or costly hosting. Learn how a blogger dramatically reduced manual moderation by using an innovative "System One" AI to define spam in plain language, offering an efficient, low-overhead solution for content creators facing similar challenges.
-
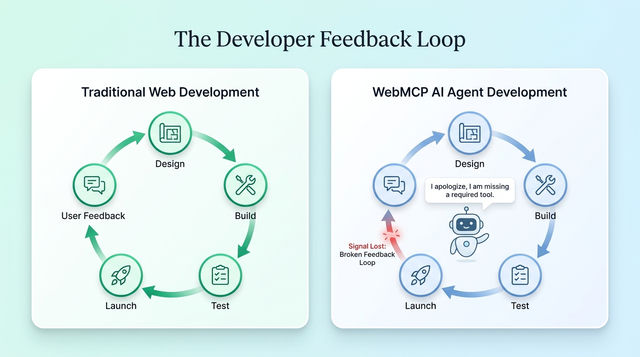
Closing the WebMCP Feedback LoopUncover the critical missing feedback loop in AI agent development on the web. This article delves into why agents fail silently when interacting with WebMCP tools, leading to blind spots for developers, and explores innovative, secure out-of-band reporting mechanisms and platform events to provide crucial telemetry, ensuring a more robust and effective "agentic web" experience for all.